I Built My Own SEO Crawler - Architecture Notes from seo-pulse
Instead of paying for Screaming Frog or Ahrefs, I built my own SEO audit tool - a Bun monorepo with a Nuxt 4 UI, a pg-boss worker that crawls and scores sites, and an MCP server so AI agents can trigger crawls and read findings. Here's the real architecture, and the parts that hurt - deploys killing workers mid-crawl, queue schema upgrades, and Docker builds dying without an error.
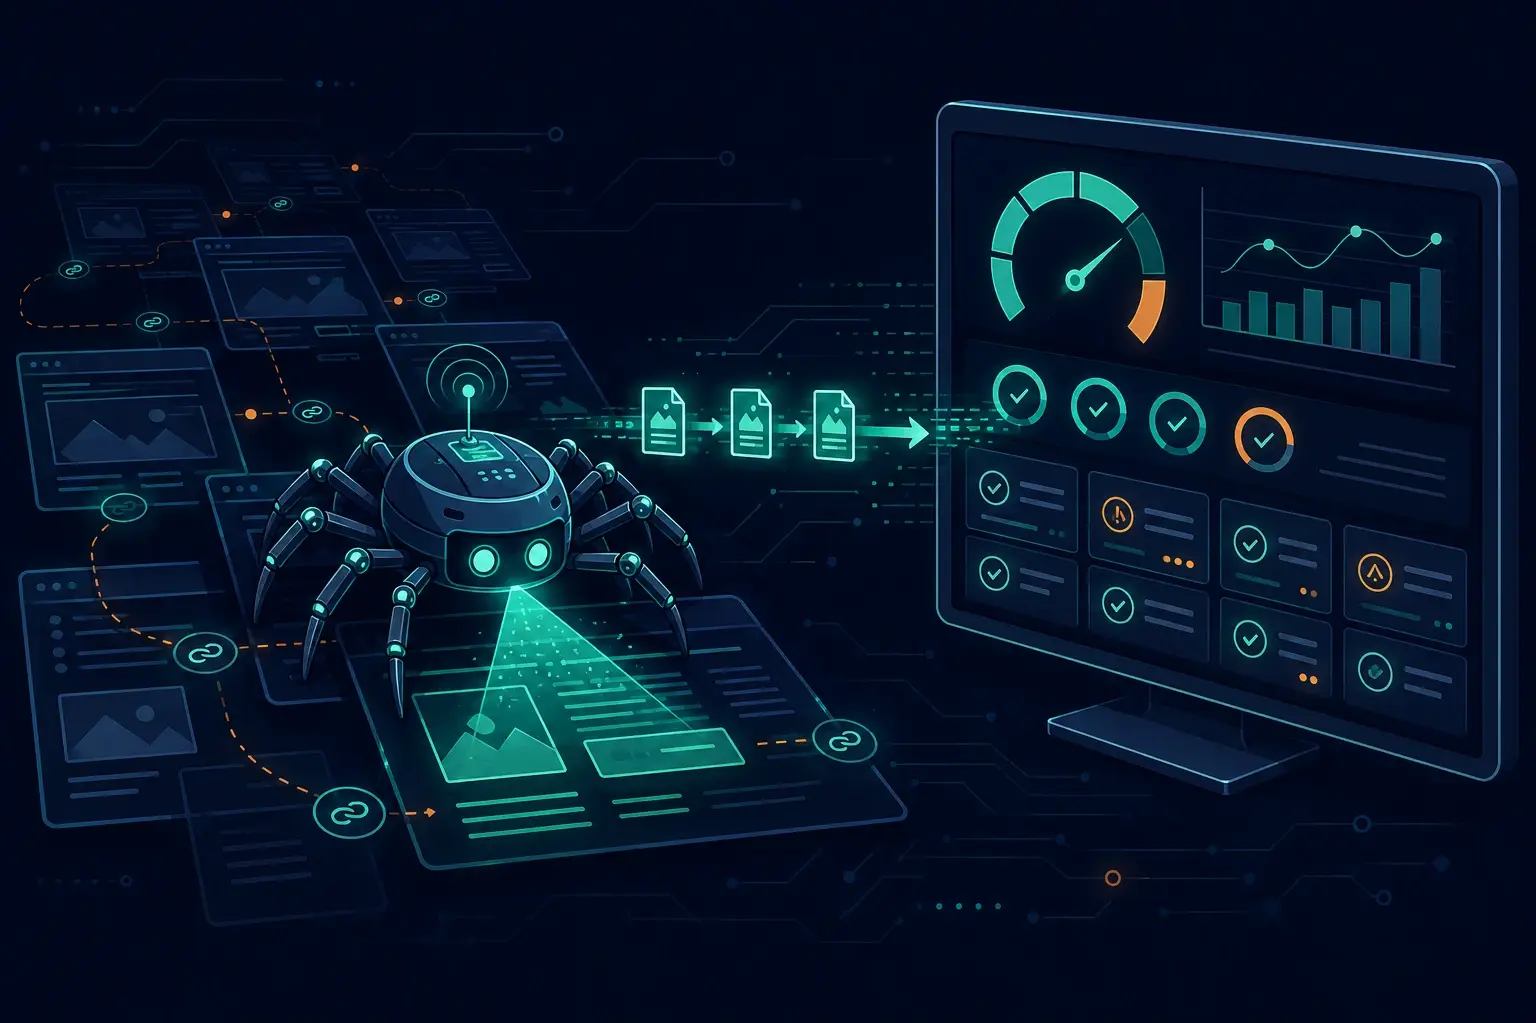
For the past months I've been building seo-pulse, a self-hosted SEO audit tool: it crawls a site, scores it across eight areas (SEO, Performance, Accessibility, Tracking, SEA, Content, Crawlability, E-Commerce), and turns the raw data into findings with step-by-step fix guides. This post is the architecture write-up I wish I'd read before starting — the real system, including the parts that broke.
Why Build One When Screaming Frog Exists?
Fair question. Screaming Frog is excellent, Ahrefs and Sistrix are excellent, and if you just need a crawl report today, buy one of those and move on. I built my own anyway, for three reasons:
Learning. I audit Shopware shops for performance and SEO as part of my client work, and I kept treating crawler output as a black box. Building the pipeline myself — robots.txt semantics, sitemap discovery, redirect chains, canonical resolution, how PageSpeed data actually maps to fixes — forced me to understand every rule I'd been quoting to clients.
Automation. Desktop crawlers are interactive by design. I wanted crawls that run on a schedule, diff themselves against the previous run, and raise an alert when a deploy quietly ships noindex to production. That's a background service with a database, not a GUI you remember to open.
AI agents. This became the biggest reason over time. Findings sitting in a dashboard still need a human to read them, prioritize them, and type them into an editor. Findings exposed through an MCP server can be pulled directly into Claude: "check the health of this project, take the top opportunity, and fix it in the codebase." No commercial tool offered that when I started — so the crawler became the data layer for an agent workflow.
The Big Picture
seo-pulse is a Bun workspace monorepo with two apps and two packages:
apps/
  web/      # Nuxt 4 UI + API routes (+ the MCP endpoint)
  worker/   # crawl, PageSpeed, scoring, PDF, cron jobs
packages/
  db/       # Drizzle schema, migrations, seed
  shared/   # types, severity model, scoring utils
The infrastructure philosophy is deliberately boring: Postgres is the only stateful service. It holds the projects, crawl runs, and findings — and it's also the job queue, because pg-boss stores its queue in a pgboss schema inside the same database. No Redis, no RabbitMQ, no S3. Deployment is a docker compose up with four services: postgres, a one-shot migrate container, web, and worker. The web app and worker only start after migrations complete, so a fresh deploy is always fully migrated.
That single-database decision paid off more than any other. Backups are one volume. Local dev is one container. And when the queue and the domain data live in the same transactional store, you can make crash-recovery guarantees that are genuinely hard with a separate broker — more on that below, because I needed them sooner than expected.
The Crawl Pipeline
A crawl is one pg-boss job (crawl.run) handled by apps/worker/src/jobs/crawl.ts, and it moves through explicit phases that are written to the crawl_runs row as it goes — site_checks → html_crawl → pagespeed → aggregation → done, together with a progress percentage. The Nuxt UI just polls that row, which means live progress reporting cost me two columns instead of a websocket layer.
Phase 1 — site checks. crawler/robots.ts fetches and parses robots.txt; crawler/sitemap.ts collects page URLs from the declared sitemaps (falling back to /sitemap.xml), bounded by a per-plan page cap. If the site declares a crawl-delay, the rate limiter honors it.
Phase 2 — HTML crawl. Each URL goes through a fetch layer (crawler/http.ts) that tracks redirect chains and response headers, then through a cheerio-based parser (crawler/html-parser.ts) that extracts everything the audit rules will need: title, meta description, headings, canonical, robots meta, Open Graph tags, structured data, images with their attributes, tracking signals. A rate-limiter.ts enforces a minimum gap per host so I'm a polite guest, and template-fingerprint.ts hashes page structure so near-identical templates can be grouped later. Everything extracted is persisted per URL — the crawl and the analysis are decoupled.
Phase 3 — PageSpeed. A subset of representative pages goes to Google's PageSpeed Insights API (with configurable concurrency, because the API is slow and rate-limited). I don't just take the score — the worker mines the individual diagnostics: LCP phase breakdown, render-blocking resources, unused JavaScript, font-display, cache TTLs. One important early bug: when PSI fails for a page, the failure is recorded visibly instead of producing a silent blank score. Silent gaps in audit data destroy trust faster than honest errors.
Phase 4 — aggregation. Audit rules run over the collected data, findings are written, area scores are computed, and the run is compared against the previous one — new high-severity issues or a score drop raise an alert.
One design decision I'd defend hard: the crawler is cheerio, not a headless browser. Parsing static HTML is an order of magnitude cheaper than driving Chromium per page, and for server-rendered sites — which is what e-commerce SEO overwhelmingly cares about — it sees exactly what Googlebot's first wave sees. The trade-off is documented honestly: client-side rendered SPAs come back looking empty, and a Cloudflare "Just a moment…" challenge can masquerade as a missing <h1>. Chromium does exist in the stack, but only in one place: the PDF report generator renders through headless Chromium, because there it's one page per report instead of one per URL.
The Findings Model
Every check is an audit: a pure function receiving an AuditContext (the parsed page data plus site-level context) and returning findings. They all register in audits/registry.ts — at last count sixty-plus rules across SEO basics (title-missing, canonical-points-elsewhere, hreflang), performance (lcp-phases, render-blocking-resources, edge-cache), accessibility, tracking (tags-before-consent, duplicate-ga4), security (insecure-form, exposed sensitive files), and e-commerce specifics.
The e-commerce rules are where a generic crawler stops and this one keeps going. A page-type-classifier.ts labels every page — Homepage, Product, Category, Cart, Checkout — and rules become context-aware: product pages without Product schema, indexable checkout pages, category pages with thin content, product variants missing a shared canonical. A root-cause-classifier.ts then groups symptom findings into "Fix Once, Impact Many" items — a faceted-navigation misconfiguration is one root cause, not four hundred individual duplicate-content findings.
Each finding carries a severity, impact points (severity-weighted — deliberately not a score out of 100, because "83/100" invites arguing about the number instead of fixing things), an explanation, a step-by-step recommendation, and evidence: the actual affected URLs and the actual offending value from the crawl. That evidence field is what later makes the MCP integration more than a gimmick — an agent gets told which pages and what exactly is wrong.
Rules being pure functions over persisted crawl data has a second-order benefit I didn't plan: adding a rule means writing one file and a test against fixture contexts. No crawling involved. The rule set grew fast because contributing to it is cheap.
The Parts That Actually Hurt
The crawler logic was the fun part. The operational edges were the education.
Deploys kill workers mid-crawl
A crawl of a large shop runs for a while. A deploy replaces the worker container. Those two facts collide: the old worker dies mid-crawl with SIGTERM, and a graceful-shutdown window doesn't help when the job needs twenty more minutes.
The fix has three layers, and all of them lean on the queue living inside Postgres:
- Boot-time resume. On startup, the worker flips every run stuck in
runningback toqueuedand re-sends the job. The flip is a single atomicUPDATE … RETURNING, so two workers booting concurrently can't double-enqueue the same run. - Idempotent crawl handler.
handleCrawlJobclears partial data and re-crawls from scratch, so resuming is just re-running. - A job-ownership guard. This one I only added after being bitten. The run row stores the pg-boss
jobIdthat currently owns it. When a crawl handler catches an error and wants to mark the run failed, the write is guarded:WHERE id = runId AND job_id = job.id. Without that, a zombie handler from the old container — killed mid-crawl, its catch block firing late — would stampfailedover a run that the new worker had already resumed and was happily crawling. I watched that exact sequence produce a "crawl failed" alert for a crawl that finished successfully. The guard turns "last writer wins" into "current owner wins".
That third bug is the kind you only meet in production, and it's why I think building this was worth more than any course on distributed systems.
The queue schema upgrade
Along the way I upgraded pg-boss from v10 to v12, and v12 has no migration path from v10's schema. Because all durable state lives in my own crawl_runs table and queues plus cron schedules are re-created at boot, the fix was radical but safe: detect a legacy schema version, DROP SCHEMA pgboss CASCADE, let pg-boss recreate it fresh, and re-enqueue from my own tables. The details deserve their own write-up — more on that separately.
Docker builds dying with no error
The deploy builds three images, and the Nuxt/Nitro production build alone peaks at several gigabytes of memory. On a host without swap, the kernel OOM-kills the build — and in Coolify that surfaces as Deployment failed: … (exit code 255) immediately after the log line ✔ Nuxt Nitro server built, with no error anywhere. I lost an evening to that, because every instinct says to look for what happened after the last log line, and the answer was in dmesg on the host. A persistent swapfile fixed it; it's now the first line of the deploy docs. Honorable mention in the same category: Bun's isolated-linker symlink layout sent Nitro's file tracer into an ELOOP, fixed by switching to the hoisted linker in the Docker build.
What an MCP Server on Top Unlocks
The newest layer is the one I'm most excited about. The web app exposes an MCP endpoint — Streamable HTTP, stateless, one server instance per request — authenticated with per-user API tokens. Because the token resolves to a real user and the tools are bound to the same access-control utilities as the UI, an agent can do exactly what its owner could do in the browser, nothing more.
The tools mirror the questions I actually ask: list_projects, get_project_health (overall score, per-area scores, open findings by severity, top opportunities), get_findings (grouped by rule, with explanation, fix recommendation, and sample URLs), compare_runs, trigger_crawl, and create_project.
In practice, from Claude Code this looks like:
"Crawl the staging shop, then compare against the last production run and tell me if the relaunch introduced any new critical findings."
The agent triggers the crawl, polls health, pulls the diff, and — because findings carry concrete evidence — can open the affected templates and fix the issues in the same session. Earlier versions of seo-pulse had "Fix with AI" boxes that generated prompts for you to copy-paste into an assistant. The MCP connector made that whole feature obsolete, and deleting it felt like the strongest possible validation of the approach: don't bring the tool's output to the agent, give the agent the tool.
Closing Thoughts
Would I recommend building your own crawler? If you need crawl results this week: no, buy one. If you audit sites professionally and want to own the rules, automate the boring parts, and plug the results into agent workflows — it's one of the highest-density learning projects I've done. The SEO rules were maybe a third of the work. The rest was the stuff that makes any long-running background system real: job ownership, crash recovery, rate limiting, memory limits, and the humility of a deploy pipeline that fails without an error message.
The stack — Bun, Nuxt 4, Drizzle, pg-boss, one Postgres — held up better than I expected. Especially the unfashionable choice: when your queue lives in the same database as your data, an entire class of distributed-systems problems collapses into UPDATE … WHERE … RETURNING.
Enjoyed this?
Get new posts as they land.
Keep reading
Claude Code in Real Client Work — Workflows, MCP, and Where It Breaks
A year of running Claude Code on actual freelance and agency projects — the workflows that hold up, why MCP is the real game changer for client work, the failure modes nobody puts in demos, and what I promise clients about AI-assisted development.
Shopware 6 Meets AI Agents - What an MCP Server for Your Shop Could Do
MCP gives AI agents a standard way to talk to real systems. Here's what an MCP server over Shopware's Admin API could look like - the tool surface, the architecture, and the honest risks of letting an agent near a live shop.
1Password for Claude - AI Agents That Log In Without Ever Seeing Your Password
1Password and Anthropic shipped a zero-exposure integration that lets Claude log into websites and finish real tasks without the model ever touching a credential. Here's how it works, what it's good for, and where the limits are.