AI-Powered Product Search in Shopware - Semantic and Vector Search That Converts
Keyword search misses what shoppers mean. Here's how to add AI semantic/vector search to Shopware 6 with embeddings - the architecture, the tradeoffs, and a practical build.
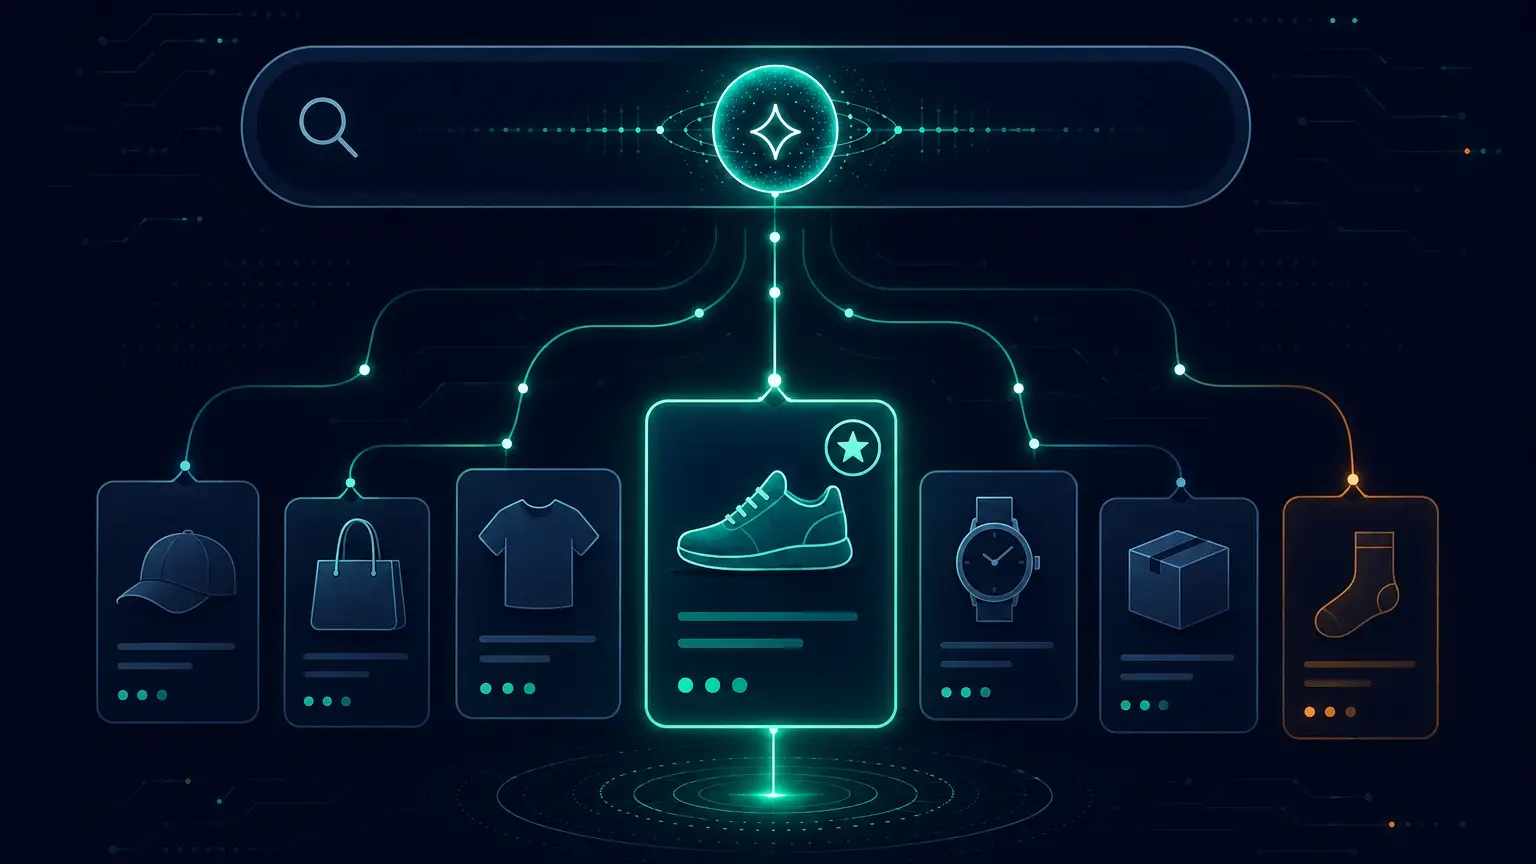
The query that finally convinced me default search was costing a client real sales was something like "warm jacket for winter hiking". Zero results. The store had plenty of insulated parkas and mountain softshells — but none of them used those exact words. The customer bounced. I watched it happen in a session recording and that was that. Shopware's built-in product search is a token matcher: it finds products whose text contains the exact words in the query. That works fine for "Nike Air Max 90". It fails badly for anything a human would actually say. Semantic search understands intent instead of tokens, and layering it onto an existing Shopware setup is more approachable than it sounds.
Why Keyword Search Loses the Sale
Full-text and BM25 search work by matching terms. The query must share vocabulary with the indexed document. When a customer describes their need in natural language — or speaks in a different register than your product copy — results fall apart.
Edge cases pile up faster than you'd expect: synonyms, plurals, abbreviations, brand names in inconsistent capitalisations, and non-English queries in a multilingual store. I've found that every store I've audited for search quality has a long tail of zero-results queries that nobody ever cleaned up, because keyword search makes the fix feel impossible — you'd have to add synonyms and aliases forever.
The practical consequence is a search results page that looks empty or irrelevant, which your analytics surface as a high zero-results rate or low click-through from search. Both are direct revenue signals.
How Semantic Search Works: Embeddings in Plain Terms
An embedding model takes any piece of text and outputs a fixed-length vector of floating-point numbers — say, 768 or 1536 dimensions. The model is trained such that texts with similar meaning end up close to each other in that high-dimensional space, regardless of exact word overlap.
Concretely: "insulated mountain parka" and "warm jacket for winter hiking" land near each other. "Running shoes" and "casual sneakers" are moderately close. "Running shoes" and "ceramic mixing bowl" are far apart.
The search operation then becomes:
- Embed the user's query → get a query vector.
- Find the stored product vectors with the highest cosine similarity to the query vector.
- Return those products, ranked by similarity score.
That's the entire core idea. Everything else — hybrid scoring, re-ranking, index freshness — is engineering around it. I like explaining it this way because it demystifies the "AI" part: at query time you're doing nearest-neighbour lookup, not running a language model on every request.
Pure Vector vs. Hybrid Search — and Why I Always Start with Hybrid
Pure vector search is great for intent-driven queries but can mis-rank for exact lookups. If a customer types a specific SKU or brand name, a vector search might surface conceptually related products rather than the exact match. For e-commerce, that's a real problem. I learned this the hard way on a build where we shipped pure vector and immediately had complaints from customers who typed exact product codes and got something adjacent instead.
Hybrid search combines a keyword/BM25 score with a vector similarity score and merges the ranked lists — commonly with Reciprocal Rank Fusion (RRF) or a weighted linear combination. You get exact-match precision from keyword search and intent-understanding from the vector branch. In practice, hybrid consistently outperforms pure vector for retail catalogs.
My rule of thumb: always start with hybrid, never pure vector. You can tune keyword vs. vector weight per category or query type once you have real traffic data. Shipping pure vector first is a trap.
Architecture in a Shopware World
Shopware runs on MySQL by default. MySQL has no native vector index. Your vector store lives outside Shopware — the question is how to bridge the two.
Option A: Search Microservice / Middleware
A small standalone service (Node/Bun, Python, or Go) does three things:
- Indexing: subscribes to Shopware product-write events (or runs a scheduled re-index), fetches product data from the Store API or Admin API, embeds it, and upserts vectors into the vector store.
- Query: exposes a
/searchendpoint your storefront calls. It embeds the query, queries the vector store, optionally merges with a keyword pass, and returns ranked product IDs. The storefront then hydrates full product data from Shopware's Store API by ID.
For a headless Shopware + Nuxt setup, this fits naturally: the Nuxt frontend calls your search service and the Store API independently. If you're using Shopware Frontends as your composable storefront, you can intercept the search composable to route through your service.
Option B: Shopware Plugin
A PHP plugin that decorates the product search route handler. The plugin embeds the query (calling out to an embedding API), queries the vector store, and merges the result with Shopware's native search. Keeps everything in one deployable unit but mixes PHP with an AI I/O path, which complicates latency management.
My recommendation: the microservice approach is easier to scale, iterate on, and debug independently of Shopware. I've used both. The plugin approach sounds appealing until you need to tune embedding models or swap vector stores — at that point you're refactoring core Shopware plumbing. Go with the plugin only if you need tight integration with Shopware's admin configuration UI.
Vector Store Options
| Store | Notes |
|---|---|
| pgvector (Postgres extension) | Simple if you already run Postgres elsewhere; good enough for catalogs up to hundreds of thousands of products |
| OpenSearch / Elasticsearch kNN | Strong hybrid story; many teams already run this for search |
| Qdrant / Weaviate / Milvus | Purpose-built; excellent filter+vector combination; more operational overhead |
| Pinecone | Managed; zero ops; per-query cost |
For most Shopware stores, pgvector or OpenSearch is the least-new-infrastructure choice. I've reached for pgvector when a client already ran a Postgres instance for something else — it's a single extension install and you're done.
Building It: Indexing Pipeline
The indexing step fetches products, builds a text representation, embeds it, and upserts into the vector store. Here's illustrative TypeScript:
// indexing.ts — run on schedule or triggered by product-written events

async function indexProducts(shopwareProducts: ShopwareProduct[]) {
  const vectors: VectorRecord[] = []

  for (const product of shopwareProducts) {
    // Concatenate the fields that describe the product semantically
    const text = [
      product.name,
      product.description,
      product.manufacturer?.name,
      product.categories?.map((c) => c.name).join(' '),
      product.properties?.map((p) => `${p.group} ${p.name}`).join(' '),
    ]
      .filter(Boolean)
      .join(' | ')

    const embedding = await embedText(text) // calls your chosen embedding API/model

    vectors.push({
      id: product.id,
      vector: embedding,
      payload: { name: product.name, price: product.calculatedPrice?.gross },
    })
  }

  await vectorStore.upsert(vectors)
}
embedText() is a thin wrapper around whichever embedding backend you chose — OpenAI's text-embedding-3-small, a self-hosted bge-m3 via a local HTTP API, or a sentence-transformers endpoint. The wrapper is the only place that changes when you swap models. I've found that making this seam explicit from the start saves a painful refactor later.
Building It: Query Path
// search.ts — called by your storefront or API route

async function semanticSearch(query: string, limit = 20): Promise<SearchResult[]> {
  // 1. Embed the user query with the same model used at index time
  const queryVector = await embedText(query)

  // 2. Vector search — returns product IDs + similarity scores
  const vectorHits = await vectorStore.search(queryVector, { limit: limit * 2 })

  // 3. Optional: keyword pass against Shopware's own search for exact matches
  const keywordHits = await shopwareSearchByKeyword(query, { limit: limit * 2 })

  // 4. Merge with Reciprocal Rank Fusion
  const merged = reciprocalRankFusion([vectorHits, keywordHits], { limit })

  // 5. Hydrate full product data from Store API by ranked IDs
  const productIds = merged.map((h) => h.id)
  const products = await fetchProductsByIds(productIds) // Store API POST /store-api/product

  return rankPreserving(products, productIds)
}
fetchProductsByIds hits the Store API's product endpoint. Importantly, Shopware's pricing, stock, and visibility rules apply at hydration time — you never bypass them by going through your own search layer. That's one of the things I appreciate about this architecture: the trust boundary stays clear.
Keeping the Index Fresh — Where Projects Quietly Rot
This is the part that gets underestimated on almost every build I've seen. The indexing pipeline gets built, the demo looks great, and then six months later someone notices that a product relaunched under a new name is returning stale results. Index freshness is where the project either holds up or quietly falls apart.
Two complementary mechanisms:
Shopware message queue / event subscribers: Write a subscriber for EntityWrittenEvent on the product entity. On write, push the product ID onto a queue. A worker processes the queue by re-embedding and upserting only changed products.
Scheduled full re-index: Run a nightly or weekly full re-index to catch anything that slipped through — category renames, property group changes, manufacturer updates that ripple across products.
Keep the re-index job idempotent: upsert by product ID, don't delete-and-recreate unless you change the embedding model (which requires a full catalog re-embed). Every time I've skipped the scheduled full re-index "to save costs", I've regretted it within a quarter.
Cost, Latency, and Multilingual Caveats
Embedding cost: Every product edit triggers a re-embed API call if you're using a hosted model. For a large catalog with frequent price updates, batch product fields carefully — don't re-embed on price-only changes if price isn't part of your embedding text. Cache embeddings; they're deterministic for the same text.
Query latency: An embedding API call adds round-trip time. Mitigate by keeping the embedding model close (self-hosted in the same region) or by caching query embeddings for popular search terms. The Shopware performance guide covers caching strategies that apply equally here.
Self-hosted vs. hosted models: Hosted APIs (OpenAI, Cohere, etc.) are operationally easy and produce high-quality embeddings, but every query and every product re-index sends data to a third party. Self-hosted models (sentence-transformers, BGE, E5 family) keep data in your infrastructure and have no per-call cost after initial deployment, but require you to manage GPU/CPU resources and model versioning. I've done both — for data-sensitive clients, self-hosted is non-negotiable regardless of the overhead.
Multilingual stores: Embeddings are language-sensitive. A model trained primarily on English will produce poor semantic alignment across German, French, or Dutch product text. Use a multilingual model (mBERT, multilingual-e5, LaBSE, paraphrase-multilingual) or maintain per-language indexes. Don't use a single English-only model for a multilingual catalog and expect reasonable results. I've seen this bite teams who benchmarked on English only and shipped to a German storefront — the semantic quality is genuinely bad in ways that aren't obvious until real users start complaining.
What's Next: RAG and Conversational Discovery
Once you have product embeddings and a retrieval layer, you have the building blocks for RAG-style product Q&A: a customer asks "What's a good gift for a trail runner who already has shoes?", a language model retrieves semantically relevant products from your index and generates a contextual recommendation. This is a natural next step once your vector pipeline is stable — I wouldn't jump straight to it, but it's a worthwhile north star to keep in mind when you're making architecture decisions early on.
Faceted filters still compose cleanly with vector search — filter by category/brand/price before the nearest-neighbour pass to keep the candidate set relevant and bounded.
Conclusion
Keyword search is a liability when your customers shop by intent rather than vocabulary. The technical path to fixing it — embeddings, a vector store, hybrid merging — is straightforward to layer onto Shopware without replacing what works. The architecture is a microservice that subscribes to product changes, keeps a vector index, and answers queries your storefront already knows how to call.
The main engineering discipline is keeping the index fresh and choosing the right embedding model for your catalog's language mix. Measure success in conversion rate and click-through from search results, not just subjective "relevance" — those are the numbers that justify the infrastructure cost.
If you're running a headless Shopware store and want to implement semantic search, or want a second opinion on your architecture before committing to a vector DB, I'm happy to talk it through.
Useful References
Enjoyed this?
Get new posts as they land.
Keep reading
Shopware 6 Meets AI Agents - What an MCP Server for Your Shop Could Do
MCP gives AI agents a standard way to talk to real systems. Here's what an MCP server over Shopware's Admin API could look like - the tool surface, the architecture, and the honest risks of letting an agent near a live shop.
Shopware 6.6 to 6.7 Migration Guide - Breaking Changes and a Safe Upgrade Path
Upgrading Shopware 6.6 to 6.7? Here are the real breaking changes - Vite, Symfony 7.4, Pinia, delayed cache - and a tested upgrade path that won't break production.
Shopware Frontends - Building a Composable Storefront with Vue and Nuxt
Shopware Frontends is the official way to build headless storefronts on Shopware 6. Learn the Vue Starter Template, Nuxt layers, composables, and the Store API architecture.